Quoted passages · Sept 2026
SMELT - Scaling Laws for Compute-Matched MoE Looped Transformers
Mostly someone else’s words. I keep it as reading, not as my own writing.
Looped Transformers increase effective depth by iterating a shared block of layers, but most evaluations compare at fixed model size, conflating architectural advantage with extra FLOPs. We study looping on Mixture-of-Experts Transformers while closely matching per-token FLOPs, total non-embedding parameters, and KV cache. Through a series of ablations, we arrive at a recipe we call SMELT (Sparse MoE Transformer, middle layers Loop Twice), which loops the middle half of layers twice while matching the unlooped Baseline on all three budgets. We scale SMELT across four sizes up to 54B non-embedding parameters and fit a separate Chinchilla-style scaling law for each architecture. SMELT’s loss drops faster with compute, saving 6.8–18.0% of training FLOPs on the compute-optimal frontier. The advantage transfers to downstream benchmarks beyond what validation loss predicts, is largest on Code, and grows with sample length and the number of in-context examples. Mechanistic analysis shows that the second visit reduces the attention sink and redirects mass toward content-relevant tokens, an inductive bias that may underlie the observed performance gains. These results show that looping can improve Transformers even under budget matching, offering a practical recipe that turns depth reuse into measurable gains. We demonstrate that depth reuse is a net win for MoE Transformers under budget matching. By searching the loop configuration space under budget matching, we identify the SMELT recipe, which loops the middle half of layers twice at a larger effective depth-to-width ratio and consistently beats the Baseline across four scales and four sparsity levels, saving 6.8–18.0% of training compute on the frontier. The advantage extends beyond validation loss: on downstream benchmarks the gain exceeds what validation loss predicts, concentrates on structured data and long samples, and grows with in-context examples. Our mechanistic probes find a consistent internal signature: the second visit reuses retrieval coordinates, amplifies residual writes, and frees attention mass from the sink. This suggests that looping acts as a refinement step rather than simply adding capacity.
Ankifying
- “The idea has drawn intense recent interest: looped models match or exceed unlooped models several times their size on arithmetic, multi-hop induction, and math [22, 54, 68], and learn algorithmic procedures in context at a fraction of the parameter count [64]. Since effective depth sets how many sequential computation steps each token receives [40, 43], looping promises reasoning capability without additional parameters.”
- Schwethelm et al. [55] control for this: they hold per-token FLOPs fixed for a dense model and find that r recurrences contribute like r 0.46 unique-block equivalents, but fixing FLOPs also shrinks the looped model’s unique parameters, so the deficit may reflect parameter loss rather than a flaw in looping itself. A clean answer requires holding three budgets all fixed at once: 1) per-token FLOPs, which set training and inference cost; 2) total parameters, which bound knowledge capacity; and 3) KV cache, which limits servable context length
- Mixture-of-Experts Transformers make this budget matching feasible: a looped model can pay for its extra visit by narrowing the hidden dimension, and because MoE decouples total parameters from per-token FLOPs [20, 56], it can recover the lost capacity by raising expert count rather than giving it up. KV cache parity is restored separately by adjusting the head size and GQA ratio. Under this matching, we search the loop design space through three ablations and find three rules: 1) loop the middle half of layers rather than the full stack, 2) give the looped model a larger effective depth-to-width ratio than the Baseline, and 3) loop twice rather than three or four times. Together these lock in a recipe we call SMELT, a Sparse MoE Transformer whose middle layers Loop Twice
- We also find that among training domains, Code benefits the most. The advantage is further amplified on longer samples and when more in-context demonstrations are available, suggesting that looping becomes more valuable as the input grows richer in retrievable structure (Section 5). To build intuition for the advantages observed above, we examine what the looped layers compute differently on their second visit. We find that the experts selected and the tokens attended to overlap substantially across the two visits, while the residual updates grow substantially larger and stay aligned, indicating that the second visit amplifies the first rather than overwriting it. Within the attention mechanism, values change more than queries and keys, and the attention sink is broadly reduced, redirecting mass toward content-relevant tokens, which may relate to the observed ICL advantage
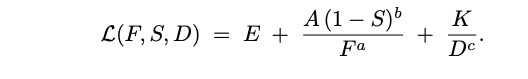 The equation, what are the components, the direction each one moves the loss when increasing/decreasing etc
- Rule of thumb for num flops per active param.
- Viterbi
- The benefits of SMELT over baseline grows with context length, the larger the validation gap is - the performance gap is even larger, and grows on structured data
- Surprising to me - The second loop “changes” the residual stream more than the initial pass does. They also showed that the second pass through usually attends to the same Keys and Queries, but different Values