Article summary · Oct 2026
What I Learned from RL and Agentic RL Interview Questions
Mostly someone else’s words, from Jiaxin Zhang: Everything about RL and Agentic RL (interview questions). I keep it as reading, not as my own writing. Read the original ↗
- Authors: Jiaxin Zhang
- Link/DOI: https://jxzhangjhu.github.io/blog/2026/everything-about-rl-and-agentic-rl/
- Date Read: 2026-10-13
- Tags:
Part I — Foundations & Problem Setup
§1 — What post-training is, and the recipe map
Key concepts.
A modern chat/reasoning model is built in two phases. Pre-training learns a base model by next-token prediction on web-scale text — broad knowledge, but no reliable instruction-following or preference for helpful, honest answers. Post-training turns that base model into something usable. It is a recipe of stages, run roughly in this order (Ouyang et al., 2022; Lambert, 2026):
- Instruction tuning / SFT — supervised fine-tuning on (instruction, response) pairs so the model follows instructions and adopts a format/voice (Wei et al., 2021).
- Reward modeling — train a reward model (RM) on human preference pairs to score responses (§4).
- Rejection sampling — sample several responses, keep the best by the RM, fine-tune on them (§6).
- Reinforcement learning — optimize the policy against a reward signal with PPO/GRPO (§7–§8).
- On-policy distillation / direct alignment — cheaper signal sources: distill a teacher on the student’s own rollouts (§6), or skip the RM/RL loop entirely with DPO (§9).
Two reward regimes run through all of this. RLHF (RL from human feedback) uses a learned reward model as a proxy for human preference — flexible, but hackable. RLVR (RL from verifiable rewards) replaces the RM with a programmatic checker — “is the math answer correct?”, “do the unit tests pass?” — which is far harder to game and underpins the reasoning models (DeepSeek-AI, 2025; the term was popularized by Tülu 3, Lambert et al., 2024).
Question: Walk through the standard post-training pipeline — what does each stage actually learn? 🎯 SFT teaches format and instruction-following; the reward model learns human preference; rejection sampling and RL push the policy toward higher-reward behavior; direct-alignment/distillation are cheaper ways to inject the same preference signal.
Question: RLHF vs RLVR — when do you not need a reward model? 🎯 When the reward is verifiable. If correctness can be checked programmatically (math, code, format), use that checker directly (RLVR) and skip the learned RM, which removes a whole failure mode (reward-model hacking).
Question (added): How much SFT is enough before switching to RL/GRPO? 🎯 Enough SFT means the model can reliably produce valid, scoreable rollouts in the right format, with nontrivial success and failure under the verifier. Once rollouts are mostly parseable and the reward has variance, switch to RL; more SFT is not automatically better because it pulls the model toward a fixed external distribution and can reduce exploration.
§2 — RL background and the math toolkit
Key concepts.
RL formalizes “learn by trial and error” as an agent acting in a Markov Decision Process (MDP), the tuple (Sutton & Barto, 2018):
- — the set of states . For an LLM, a state is the whole context so far: the prompt plus every token generated up to now.
- — the set of actions . For an LLM, an action is the next token, so is the vocabulary (often tokens).
- — the transition dynamics, the probability of the next state. Plain text generation is deterministic (append the token); for agents it also includes the environment’s reply to a tool call.
- — the reward. In RLHF/RLVR it is usually given only at the end of a sequence (terminal and sparse), not per token.
- — the discount factor, weighting near-term vs long-term reward.
At step the agent samples an action from its policy (the LLM with parameters ), gets reward , and moves to . A full episode is a trajectory . The return from step is the discounted sum of future rewards,
and the training objective is the expected return under the policy,
Value functions summarize that expected future. The state-value is the expected return from a state; the action-value is the expected return from taking a specific action in that state and following afterwards:
Their difference is the advantage — how much better an action is than the policy’s average behavior in that state:
The policy-gradient theorem (a one-line derivation). We cannot differentiate through the sampled reward, but we can differentiate the probability of the actions we took. The log-derivative trick, , rewrites the gradient of the objective as an expectation we can estimate from rollouts (Sutton et al., 2000):
In words: raise the log-probability of actions with positive advantage, lower it for actions with negative advantage. This single equation underlies REINFORCE, PPO (§7), and GRPO (§8); those algorithms differ mostly in how they estimate and how they keep each update stable. Estimating well is the job of GAE (§7); replacing the learned value baseline with a group mean is the idea of GRPO (§8).
Three probability tools recur throughout RL training:
- Cross-entropy / KL / entropy / MLE — one identity ties them together (next question), and it is the same objective behind pre-training and SFT.
- Monte-Carlo estimation — approximate an expectation by averaging samples, . Every policy gradient above is a Monte-Carlo estimate.
- Importance sampling / rejection sampling — two ways to use samples that did not come from the distribution you actually care about (next questions). This is the formal basis for reusing off-policy rollouts.
Question (Algo-2): How do cross-entropy, KL divergence, entropy, and MLE relate? 🎯 One identity: . Minimizing cross-entropy or KL over is the same thing (since is constant in ); and maximum-likelihood training is exactly minimizing .
Question (Algo-4): What are importance sampling and rejection sampling, and how are they used in RL? 🎯 Both are Monte-Carlo techniques for “samples from the wrong distribution.” Importance sampling reweights off-policy samples by a probability ratio (used to reuse slightly-stale rollouts); rejection sampling keeps/drops samples to match a target (used for data filtering / best-of-N).
Question (added): Online vs offline RL — and how does that map to LLM post-training? 🎯 Online RL collects fresh data from the current policy during training (PPO, GRPO, RLVR); offline RL learns from a fixed, pre-collected dataset with no new interaction (DPO-style preference tuning, offline RL algorithms). “On-policy vs off-policy” is a separate axis: whether the data came from the current policy or another one.
§3 — Algorithm families: value-based, policy-gradient, actor-critic
Key concepts.
Classical RL gives three answers to “how do we improve the policy?”, and modern LLM RL is the end of a long evolution through them.
1. Value-based methods (Q-learning, DQN). Learn the optimal action-value — the best expected return achievable after taking in — and act greedily, . There is no explicit policy: the policy is implied by the argmax over the learned values. This is elegant for small, discrete action spaces (the next question walks through how it actually works).
2. Policy-gradient methods (REINFORCE). Parameterize the policy directly and ascend the policy gradient from §2. No values are learned; you just sample trajectories and push up the log-probability of high-return actions. Flexible and able to produce a stochastic policy, but the raw estimator has high variance.
3. Actor-critic (A2C, PPO). Keep an explicit policy (the actor) and learn a value function (the critic) whose only job is to provide a low-variance baseline/advantage for the actor’s gradient. This is the best of both — an explicit, stochastic, sample-able policy with a variance-reducing value estimate — and it is the template PPO (§7) is built on.
LLM RL lives almost entirely in families 2 and 3 (and GRPO, §8, even drops the critic for a Monte-Carlo group baseline). The questions below make concrete why a pure value-based approach is a poor fit for language, and trace the evolution from Q-learning all the way to GRPO.
Question (added): How does a pure value-based method (Q-learning / DQN) actually work? 🎯 Learn by bootstrapping toward the Bellman target , and act by taking the argmax. The policy is never represented — it falls out of the values. This is great for small discrete action spaces, and is exactly what breaks for token-by-token, sequence-level LLM generation.
Question (Algo-1): Why use actor-critic rather than a pure critic (value-based) method? 🎯 Because LLM generation is a huge sequence-level decision problem with sparse terminal rewards. Single-token argmax over the vocabulary is not the core issue — the core issue is that bootstrapped Q-learning over long text trajectories is impractical and unstable. An explicit policy samples trajectories directly; the critic, when used, is only a variance-reduction device.
Question: Value-based vs policy-gradient vs actor-critic — when does each break down? 🎯 Value-based: breaks in large/continuous action spaces and only yields a deterministic greedy policy. Pure policy-gradient: unbiased but high variance, sample-inefficient. Actor-critic: combines them — explicit (stochastic) policy with a variance-reducing critic — at the cost of a second model and critic bias.
Part II — Rewards & Preferences
§4 — Preferences and reward modeling
Key concepts.
When “good” is subjective, we cannot write a reward function — we learn one from human comparisons. The standard pipeline collects preference pairs: for a prompt , a human (or AI) judges response better than . A reward model (RM) — usually the base model with a scalar head — is trained so that preferred responses score higher, via the Bradley–Terry model (Bradley & Terry, 1952), which says the probability that beats is
so the RM is trained by minimizing (Ouyang et al., 2022). Only differences are learned, so the reward scale is arbitrary (this matters for normalization later).
Beyond a learned scalar RM, two cheaper preference sources are now common:
- LLM-as-judge — prompt a strong model to compare/score responses (Zheng et al., 2023). Cheap and flexible, but biased.
- Rubric / Constitutional feedback — score against an explicit written rubric or constitution (Bai et al., 2022), improving consistency and interpretability.
| Reward source | Cost | Strength | Main weakness |
|---|---|---|---|
| Learned scalar RM | medium (collect prefs + train) | dense, fast at inference | overoptimization, distribution shift |
| LLM-as-judge | low | flexible, no training | position/verbosity/self bias, miscalibration |
| Rubric / constitutional | low–medium | consistent, auditable | rubric design effort |
| Verifiable checker (§5) | low (if checkable) | lower attack surface, exact | only for verifiable tasks; verifier can be exploited |
Table 3. Reward/verifier sources and trade-offs.
Question: How is a reward model trained, and why does only the difference in scores matter? 🎯 Train it on preference pairs with a Bradley–Terry (logistic) loss on the score difference; because the loss only sees , the absolute scale and offset are unidentifiable — the RM learns relative quality, not an absolute score.
Question: What goes wrong with LLM-as-judge, and how do you harden it? 🎯 Judges have systematic biases — position, verbosity, self-preference — and are often miscalibrated. Harden with randomized ordering, reference answers/rubrics, pairwise rather than absolute scoring, and calibration checks against human labels.
§5 — Verifiable rewards, regularization, and reward hacking
Key concepts.
A reward is only as good as its resistance to being gamed. Reward hacking (a.k.a. specification gaming) is when the policy maximizes the measured reward without achieving the intended goal — a classic, general RL failure (Amodei et al., 2016; Skalse et al., 2022). With a learned RM this is acute: optimize hard enough and the policy finds the RM’s blind spots, so measured reward rises while true quality falls — reward-model overoptimization, which Gao et al., 2023 showed follows a predictable scaling curve (true reward goes up, peaks, then declines as KL from the reference grows).
Two defenses:
- Verifiable rewards (RLVR). Where correctness is checkable — math answers, unit tests, format regex — score with the checker instead of an RM. This reduces the attack surface, but it moves the attack surface onto the verifier itself (DeepSeek-AI, 2025; Lambert et al., 2024).
- KL regularization. Penalize divergence from a frozen reference policy so the model cannot wander into RM blind spots (§7’s KL-to-reference). This bounds the destination, trading a little reward for staying in-distribution.
The catch: verifiable ≠ unhackable. Test suites can be satisfied by degenerate solutions, format rewards by empty reasoning, and “judge” verifiers by sycophantic phrasing. The reward/verifier is the real attack surface of the whole system.
Question (Algo-3): How should you design rewards for different RL settings? 🎯 Match the reward to what you can actually verify. Prefer a programmatic verifiable reward when the task has ground truth; use a learned RM (or LLM-judge/rubric) only for genuinely subjective qualities; and always design against the cheapest exploit, not just the intended behavior.
Question: How do you detect reward hacking in practice? 🎯 Watch for the tell-tale divergence: measured reward keeps rising while held-out quality stalls or drops. Concrete signals — sudden reward jumps, response-length blow-ups, KL-from-reference spiking, and qualitative inspection of high-reward samples.
§6 — Rejection sampling and on-policy distillation
Key concepts.
Not every preference signal needs the full online RL loop. Two lighter-weight techniques sit between SFT and PPO/GRPO.
Rejection sampling (a.k.a. best-of-N fine-tuning). Sample responses per prompt from the current model, score them (RM or verifier), keep the best, and fine-tune on those with the ordinary SFT loss (Touvron et al., 2023). It is the simplest way to turn a reward into improvement — no critic, no clipping, no importance sampling — and is a strong, stable baseline. Its limit: it only ever imitates the best of what the current model can already produce, so it cannot explore as far as on-policy RL.
On-policy distillation (OPD). A teacher provides a dense signal on the student’s own rollouts: the student generates a trajectory, and the teacher scores/relabels it token-by-token (e.g. teacher log-probs as the target), which the student distills against (Agarwal et al., 2023, generalized knowledge distillation). The key word is on-policy: unlike vanilla distillation on a fixed corpus, the student learns to fix its own mistakes in the states it actually visits, which closes the train/test distribution gap that plagues off-policy distillation.
Question (Algo-17): How does on-policy distillation improve on plain RL or plain SFT, and where is it used? 🎯 It combines RL’s on-policy exploration with SFT’s dense, low-variance signal: the student samples its own trajectories (like RL) but learns from a teacher’s per-token targets (like SFT) instead of a sparse scalar reward — cheaper and more stable than RL, less distribution-mismatched than off-policy distillation.
Question (added): What is the difference between rejection-sampling fine-tuning and inference-time best-of-N? 🎯 Same operation, different place. Inference-time best-of-N spends compute at test time and returns the best sample; rejection-sampling fine-tuning uses best-of-N to create new training data, then changes the model weights so future samples improve without paying the test-time cost every time.
Part III — Policy Optimization Algorithms
§7 — The PPO family and trust regions
Key concepts.
Reinforcement learning for language models optimizes a policy (the model) to maximize expected reward. The workhorse is the policy gradient: instead of differentiating through a reward we cannot differentiate, we push up the log-probability of actions that turned out better than expected. For a trajectory ,
where is an advantage — how much better action was than the policy’s average at state . This is the REINFORCE estimator (Williams, 1992) made practical by the policy-gradient theorem (Sutton et al., 2000). Using the advantage instead of the raw return is the single most important variance-reduction trick; estimating it well is the job of GAE (below).
The problem with vanilla policy gradients is step size: one large, badly-scaled update can move the policy into a region where its own samples are no longer informative, and training collapses. Trust-region methods fix this by limiting how far each update may move the policy. TRPO (Schulman et al., 2015a) makes this explicit — maximize the reward subject to a hard KL constraint:
where is the importance-sampling ratio that lets us reuse samples from the slightly-older policy .
PPO (Schulman et al., 2017) replaces the hard constraint with a cheap clipped surrogate objective that approximates the trust region with first-order methods:
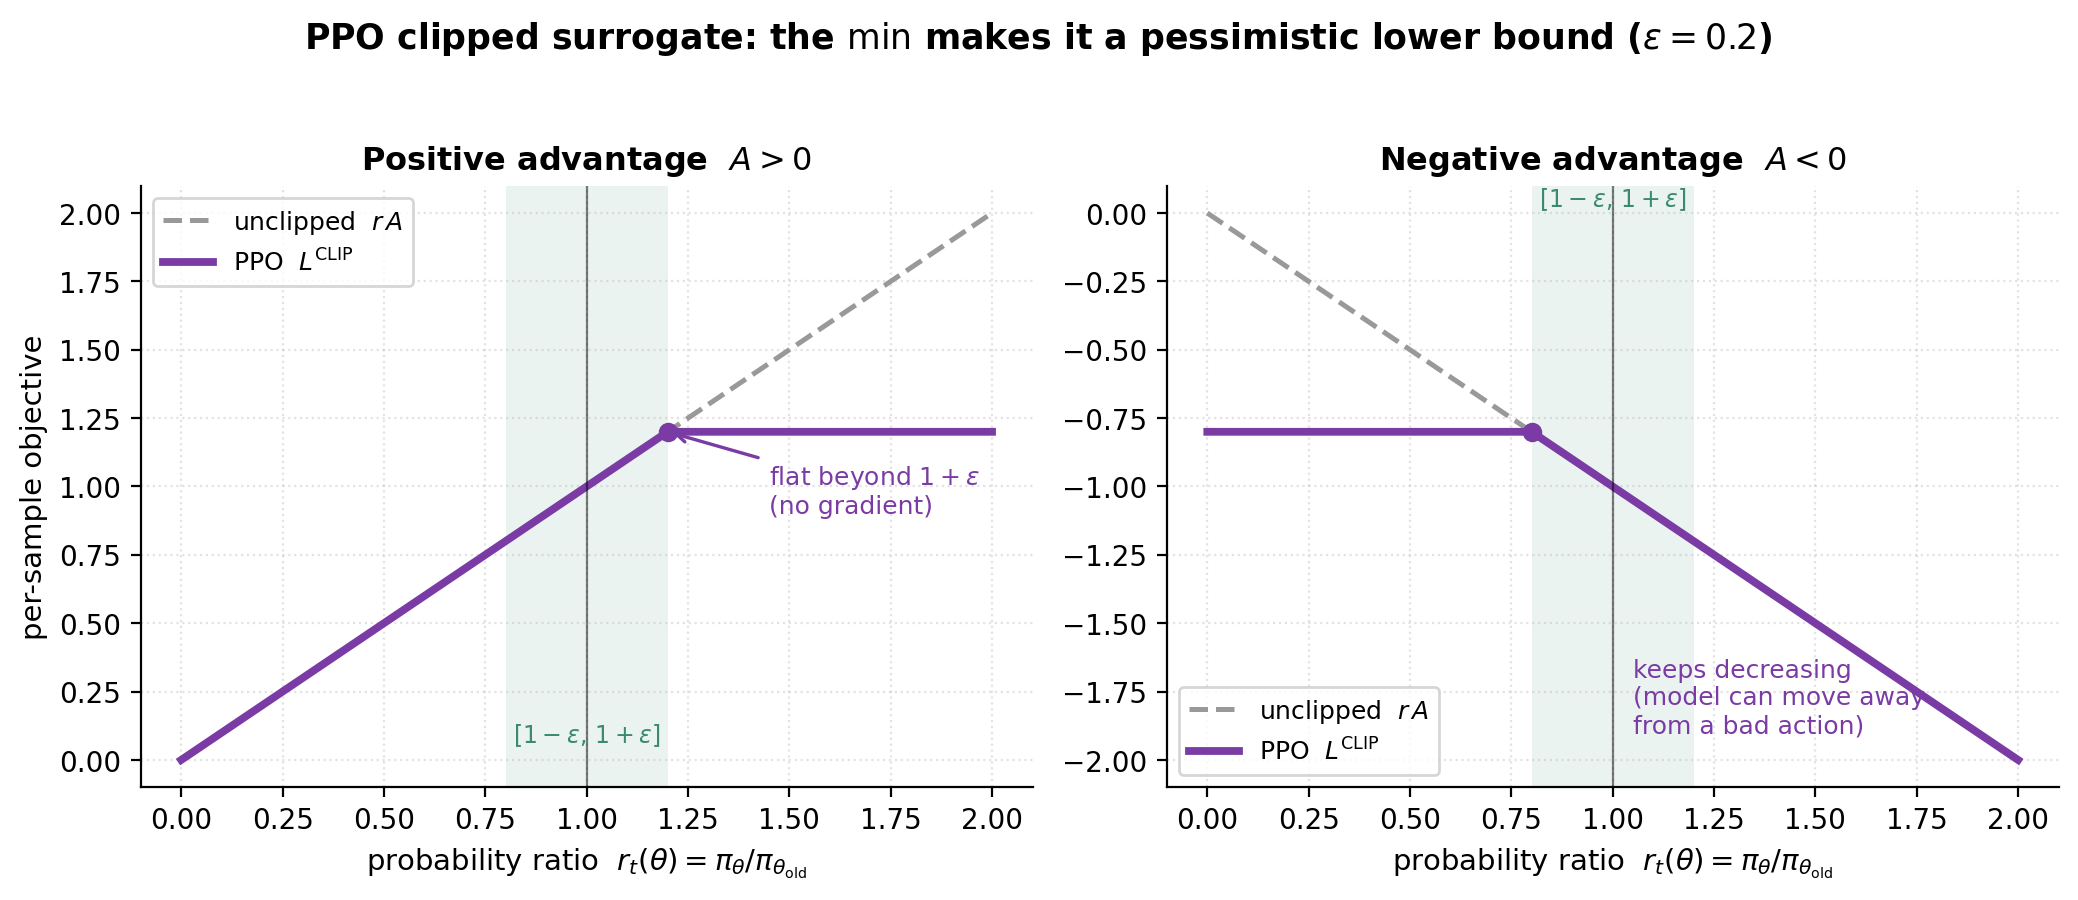 Figure 2. The clipped surrogate for (left) and (right). Inside it follows the unclipped ; outside, the outer flattens the upside (left) while still letting the policy move away from bad actions (right). This asymmetry is exactly what makes a pessimistic lower bound.
The advantage is typically estimated with Generalized Advantage Estimation (Schulman et al., 2015b):
which interpolates between low-variance/high-bias () and high-variance/low-bias () advantage estimates.
In RLHF, PPO does not optimize the raw reward model score. It optimizes the reward model minus a KL penalty to a frozen reference policy, which keeps the model from drifting into degenerate, reward-hacking text (Stiennon et al., 2020; Ouyang et al., 2022):
This PPO recipe — actor + critic + reward model + reference model — is the canonical RLHF setup (Lambert, 2026, Policy Gradient chapter). It is powerful but memory-heavy (four models in play); the next section (§8, GRPO) is largely a reaction to that cost.
Question: What is PPO’s clipping actually defending against, and where does the min come from?
🎯 Clipping caps how much one update can change the policy per token; the outer min makes the objective a pessimistic lower bound so the update only “trusts” changes inside the clip range.
Question: What does CISPO change about PPO/GRPO clipping, and why? 🎯 PPO/GRPO clipping makes the objective flat in the reward-improving direction once the ratio crosses the clipped side; CISPO instead clips the importance-sampling weight while keeping the log-prob gradient flowing through every token, preserving rare-but-pivotal updates.
Question: TRPO vs PPO vs the “staleness bound” in async RL — how are they the same idea? 🎯 All three bound how far the behavior (sampling) policy may diverge from the policy being updated; they differ only in how the bound is enforced.
Question (added — not in the source set, but worth knowing): Why optimize the advantage instead of the raw reward/return, and what do γ and λ trade off in GAE? 🎯 Subtracting a baseline to form the advantage cancels the high-variance part of the gradient that does not depend on the action; γ and λ then trade bias against variance in estimating it.
§8 — GRPO and the variant zoo
Key concepts.
PPO’s biggest practical cost is the critic: a second network, about the size of the policy, that must be trained alongside it to estimate for the advantage. GRPO (Group Relative Policy Optimization), introduced in DeepSeekMath (Shao et al., 2024) and made famous by DeepSeek-R1 (DeepSeek-AI, 2025), removes the critic entirely. The idea: for each prompt, sample a group of responses, score them, and use the group as its own baseline. The advantage of response is just its reward standardized within the group:
Everything else looks like PPO — the same clipped ratio — but with this group-relative advantage and (in the original formulation) a KL-to-reference penalty added directly to the loss rather than folded into the reward:
The KL term uses the low-variance, always-positive k3 estimator (Schulman, 2020): .
This trade — a learned critic for a Monte-Carlo group baseline — is why GRPO became the default for RLVR/reasoning: it is cheaper, simpler, and works well when you can afford several rollouts per prompt. The “variant zoo” (Table T1) is then a sequence of small fixes to GRPO’s known biases.
Insight box — “Drop the critic, keep the baseline.” GRPO’s advantage is a baseline-subtracted reward; the group mean replaces the value network. The cost moves from a second model to extra rollouts.
| Method | Year | Key change vs GRPO | Known weakness |
|---|---|---|---|
| GRPO (Shao 2024) | 2024 | group-mean baseline, no critic; KL in loss | std/length biases (below) |
| Dr. GRPO (Liu 2025) | 2025 | removes std- and length-normalization | needs careful reward scaling |
| DAPO (Yu 2025) | 2025 | clip-higher, dynamic sampling, token-level loss, overlong shaping; drops KL | more hyperparameters |
| GSPO (Qwen 2025) | 2025 | sequence-level importance ratio, clipping, and optimization | coarser credit per token |
| CISPO (MiniMax 2025) | 2025 | clip the IS weight, keep all-token gradient (see §7) | weight clipping tuning |
Table 4. The main GRPO variants. Each is a targeted fix to a specific GRPO bias; many more exist, but these four cover the ideas that recur in practice.
Question (Algo-5): How is the GRPO/PPO advantage computed, why subtract a baseline, and must you divide by std? 🎯 Advantage = reward minus a baseline (the group mean in GRPO); subtracting the baseline cancels the high-variance, action-independent part of the gradient. Dividing by std is optional — it stabilizes scale across prompts but introduces a difficulty bias that Dr. GRPO removes.
Question (Algo-8): Why does GRPO add a KL term, how is it computed, and why do DAPO/GSPO drop it? 🎯 The KL-to-reference anchors the policy to the base model so RL doesn’t degrade general ability; it’s computed with the k3 estimator. RLVR-scale runs (DAPO/GSPO) drop it because, with a verifiable reward, the leash mostly prevents the model from moving far enough to learn.
Question (Algo-13): What do the GRPO variants (Dr. GRPO, DAPO, GSPO, CISPO, …) each fix? 🎯 Each patches a specific GRPO bias: Dr. GRPO removes std/length normalization bias; DAPO adds clip-higher + dynamic sampling + token-level loss + overlong handling and drops KL; GSPO moves the importance ratio to sequence level for MoE stability; CISPO clips the IS weight to keep all-token gradients.
Question (Algo-12): How do you set group size, learning rate, PPO epochs, and generation length? 🎯 Group size 8–16 (bigger = better baseline, more compute); lr ~1e-6 (RL is touchy); PPO epochs ≈ 1 (more reuse = more off-policy = unstable); generation length set to fit the task’s reasoning budget.
§9 — Direct alignment (DPO and friends)
Key concepts.
PPO/GRPO are online: you sample from the current policy, score, and update. Direct alignment asks whether we can skip the reward model and the sampling loop entirely and just optimize on a fixed set of preference pairs. DPO (Direct Preference Optimization, Rafailov et al., 2023) shows you can. The trick is algebraic: the KL-regularized RLHF objective has a known closed-form optimum,
which you can invert to write the reward in terms of the policy: . Substituting this into the Bradley–Terry preference likelihood makes the partition function cancel, leaving a simple supervised loss on preference pairs :
So DPO’s “reward” is implicit: the quantity is the reward the policy is implicitly being trained against — “your language model is secretly a reward model.” No RM, no rollouts, no online loop; just a contrastive log-likelihood. That simplicity is why DPO is the default for cheap, stable preference tuning.
Question (Algo-10): What is DPO’s reward, can DPO be over-optimized, and how do you fix it? 🎯 DPO’s implicit reward is . It has no explicit RM to hack, but the fixed preference objective can still be over-optimized or exploited: likelihood displacement, length exploitation, and off-distribution drift. Fixes: keep an SFT/NLL anchor, length-normalize, use on-policy or iterative preference data, or conservative variants.
Question: DPO vs PPO/GRPO — when do you reach for which? 🎯 DPO when you have a fixed preference set and want cheap, stable tuning with no RM or rollouts; online RL (PPO/GRPO) when you have a reward signal you can query during training — especially a verifiable one — and need exploration beyond the preference data.
Part IV — Reasoning, Test-Time Scaling & Evaluation
§10 — RLVR and reasoning
Key concepts.
The reasoning models (OpenAI o1, DeepSeek-R1) are the headline result of RLVR: take a base model, give it a verifiable reward (math answer correct? tests pass?), and run large-scale RL — and long chain-of-thought, self-correction, and “thinking” emerge (DeepSeek-AI, 2025). The mechanism is simple to state: the policy is rewarded only for correct final answers, and the only way to raise its success rate on hard problems is to generate longer, more careful reasoning — so RL selects for it. Chain-of-thought itself (Wei et al., 2022) is the substrate; RLVR amplifies it.
A central, hotly-debated question is whether RL adds new capability or only sharpens what the base model already has. The evidence leans toward sharpening: Yue et al., 2025 find that RLVR improves pass@1 but often does not expand pass@k at large — i.e. RL concentrates probability on solutions the base model could already occasionally sample, rather than discovering genuinely new ones. This connects to two related entropy stories. Entropy collapse studies how reasoning RL can rapidly reduce policy entropy and plateau; The Entropy Mechanism of RL for Reasoning LMs proposes Clip-Cov / KL-Cov to control high-covariance tokens and preserve exploration (Entropy Mechanism, 2025). A complementary line treats entropy as an exploration signal: Reasoning with Exploration finds that high-entropy regions often coincide with turning points, self-verification/correction, and rare reasoning behaviors, and adds a clipped, gradient-detached entropy term to the advantage to encourage exploratory reasoning rather than blindly maximizing policy entropy (Reasoning with Exploration, 2025).
Question (Algo-18): At which training stage does reasoning ability appear? 🎯 The latent ability is laid down in pre-training; RL post-training (RLVR) elicits and amplifies it. RL does not teach math from scratch — it reshapes the base model’s distribution toward reliably using the reasoning it already partially has.
Question (Algo-15): Can RL expand an LLM’s capability boundary, or only sharpen it? 🎯 Mostly sharpen, within current methods — RL raises the probability of already-reachable solutions more than it discovers new ones. Whether prolonged/curriculum RL can genuinely expand the boundary is an open research question with early positive signs.
§11 — RL vs test-time scaling
Key concepts.
There are two distinct ways to spend compute to get better answers. RL (train-time) reshapes the weights so the model is better on average. Test-time scaling (TTS) spends more inference compute on a fixed model — longer chains-of-thought, sampling many solutions and selecting (best-of-N, majority vote), or search — to get a better answer on this particular query (Muennighoff et al., 2025; OpenAI o1, 2024). They are complementary: RL raises the curve, TTS moves along it at inference.
Their exploration differs too (Algo-6). RL explores in weight space over training — it samples trajectories, and the reward gradient slowly moves the policy toward regions of higher expected reward; exploration is governed by policy entropy and is consumed as entropy collapses (§10). TTS explores in output space at inference — for one prompt it samples diverse candidates (high temperature, many rollouts) and selects, with no weight change; its “exploration” is bounded by the model’s current distribution and the inference budget.
Question (Algo-6): How do RL training and test-time scaling each explore? 🎯 RL explores across training by sampling trajectories and shifting the policy toward high-reward regions (exploration limited by policy entropy, spent over many steps). TTS explores at inference by drawing many diverse samples for a single query and selecting among them (no weight update, limited by the inference budget and the current model’s diversity).
Question (Algo-16): How do you scale the RL training frontier (cf. ProRL)? 🎯 Keep exploration alive and train much longer. ProRL-style results suggest that with entropy control, KL resets, diverse/curriculum data, and prolonged training, RL can reach reasoning the base model does not show even at high pass@k — pushing beyond the “sharpening only” regime.
Question (Algo-19): From DeepSeek-R1 to V3/V3.2/V4 — what changed in the RL, and what’s different about MoE RL? 🎯 DeepSeek-R1 made large-scale RLVR on an MoE base visible; V3.2 moved toward specialist distillation plus mixed RL with GRPO and MoE-specific stabilizers; V4 publicly appears to separate domain-expert cultivation (SFT+GRPO) from unified model consolidation via OPD. MoE RL is harder because expert routing makes training–inference consistency and per-token ratios fragile.
§12 — Evaluation: how do you know RL actually helped?
Key concepts.
RL is easy to fool yourself with. A training reward curve going up is not enough: maybe the model found a verifier exploit, got longer, overfit the public tests, or improved only under a larger test-time budget. Evaluation has to separate training signal, held-out capability, exploration, and systems health. The cleanest question is: under a fixed inference budget and a held-out verifier, does the trained policy solve more tasks without regressions elsewhere?
All model comparisons should be budget-controlled: same prompts, same decoding settings, same sampling count, same tool limits, and the same inference budget. Otherwise you may be measuring “spent more test-time compute” rather than “the model got better.”
For reasoning, always separate pass@1 from pass@k / best-of-N / majority vote. Pass@1 measures how much probability mass the policy puts on a correct solution; pass@k measures whether a correct solution exists somewhere in the model’s distribution. This distinction is exactly what lets you test “sharpening vs frontier expansion” (§10). For agents, also measure trajectory properties: success rate, turn count, tool errors, side effects, cost per success, and environment reset failures.
Question (added): How do you evaluate whether an RL run improved the model rather than overfit the verifier? 🎯 Use a held-out, contamination-controlled eval under a fixed inference budget; track pass@1/pass@k, reward, KL/entropy/length, and manually audit top-reward and random samples. If reward rises but held-out quality stalls or drops, you optimized the proxy, not the task.
Question (added): What should you log during a real GRPO/RLVR run? 🎯 Log enough to diagnose reward hacking, entropy collapse, off-policyness, and systems starvation: reward, KL, entropy, clip fraction, ratio distribution, length, group reward std, all-pass/all-fail rate, rollout throughput, trainer idle time, queue size, staleness, and held-out quality.
Question (added): An RL/GRPO run is stable and reward rises, then collapses. How do you debug it — what do you watch in W&B, and what are the usual causes? 🎯 Collapse is almost always one of four families: entropy/exploration collapse, reward/verifier hacking, off-policy / trust-region blow-up, or a systems–numerics bug. Don’t guess — overlay a fixed panel (train reward vs held-out, entropy, KL-to-ref, clip fraction, ratio histogram, grad-norm, length, group-reward std, all-pass/all-fail), find which curve turned first, and read the top-reward rollouts at the collapse step. The shape and timing usually name the cause.
Part V — Agentic RL
§13 — From single-turn RLHF to multi-turn agentic RL
Key concepts.
Everything so far assumed a single turn: prompt in, one response out, one reward. An agent is different — it acts over many steps in an environment: call a tool, read the result, decide the next action, repeat, until a task is done. RL for agents keeps the same policy-gradient machinery but the episode is now a trajectory where actions are tool calls / messages and states include tool outputs. Two things change fundamentally: the reward is usually terminal and sparse (did the whole task succeed?), and credit must be assigned across many steps and tokens.
A practical subtlety unique to LLM agents: a trajectory interleaves model-generated tokens (actions, reasoning) with environment-returned tokens (tool outputs, observations). You must mask the observation tokens out of the loss — the model should not be trained to “predict” text the environment produced, only its own actions. Getting this masking wrong is a common and silent bug.
Question: Why is credit assignment harder in multi-turn agentic RL, and what are the options? 🎯 Because one sparse terminal reward must be distributed over many steps and tokens, with no per-step supervision. Options span a spectrum: trajectory-level (one advantage for the whole episode, simple but high-variance) to step/turn-level (a value or process reward per step, lower-variance but needs a critic or process verifier).
Question: What changes in GRPO when you go from single-turn to multi-turn tool use? 🎯 Mechanically little — same group-relative advantage and clipped ratio — but you (1) define the episode as a full tool-interleaved trajectory, (2) mask environment/observation tokens from the loss, (3) usually apply one trajectory-level advantage to all action tokens, and (4) handle variable-length, long trajectories (truncation, turn limits, and the long-tail rollout problem of §17).
§14 — Environments: the bottleneck, and difficulty ≠ trainability
Key concepts.
For single-turn RLHF the “environment” is trivial — score a response. For agents, the environment is an executable, stateful, verifiable world, and building enough of them is the real constraint. The field’s working thesis: agentic RL is bottlenecked by environments, not algorithms — benchmarks give a few hundred hand-built tasks (enough to evaluate, nowhere near enough to train), so a fast-growing line of work synthesizes environments at scale. (This post’s companion, Environment Scaling for Agentic RL, is a deep dive; here we only need the one idea that connects to training.)
That idea is difficulty ≠ trainability. A task only produces a learning signal when its outcome is uncertain under the current policy. For a binary verifiable reward, the per-task variance is , where is the policy’s pass rate:
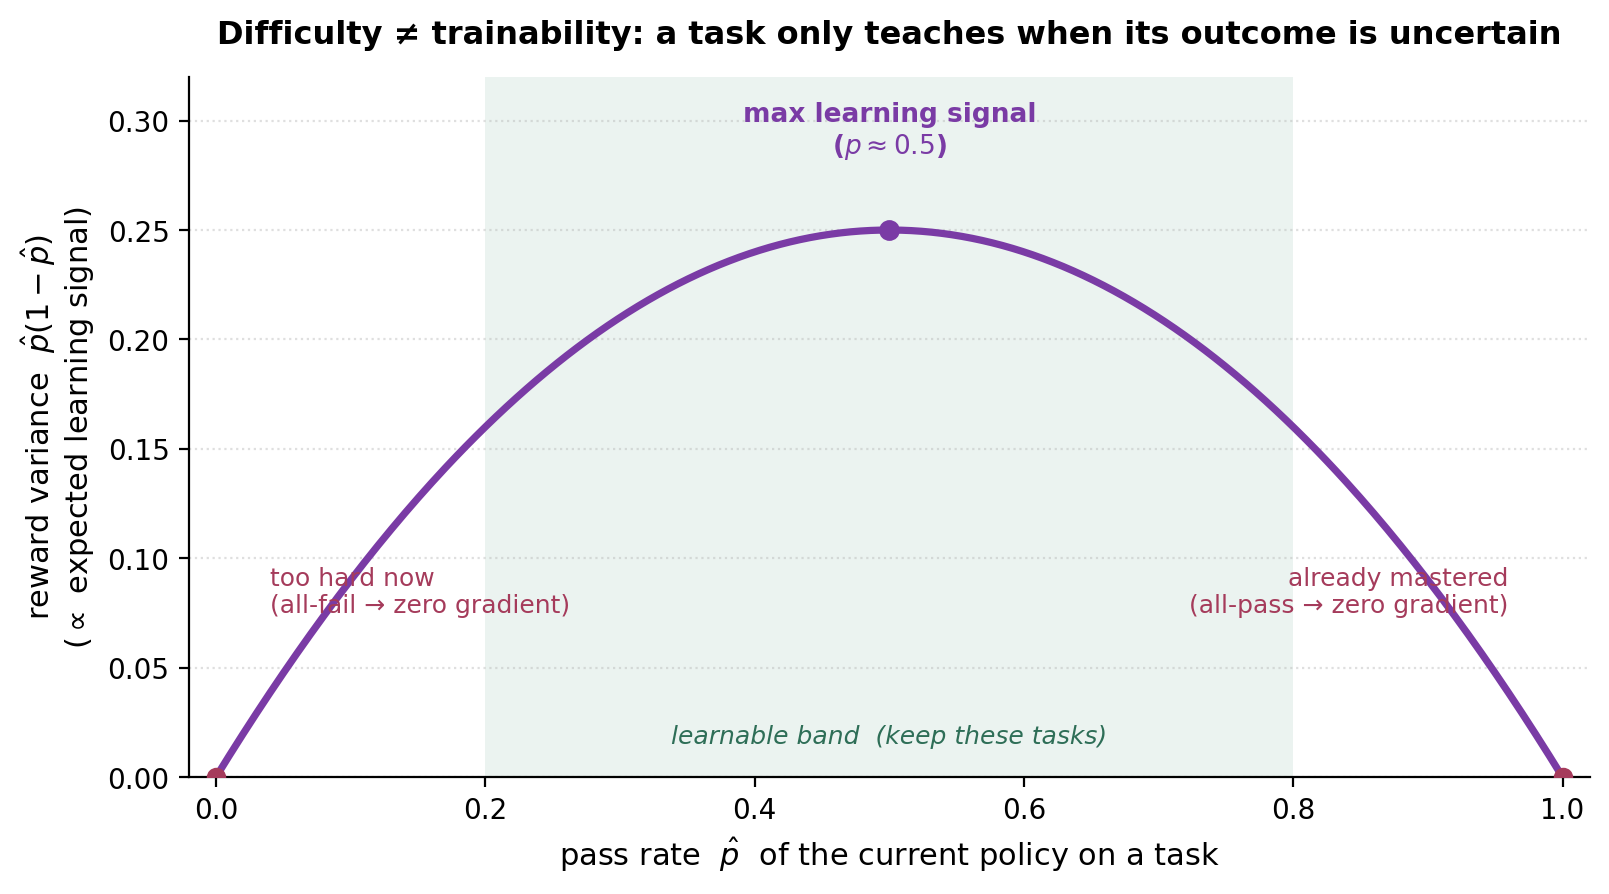 Figure 3. Reward variance is maximized at and zero at the extremes. A task the model always fails () or always passes () yields zero advantage and zero gradient — it teaches nothing right now, regardless of how “hard” it is in absolute terms.
Question: Why do people say agentic RL is “bottlenecked by environments, not algorithms”? 🎯 Because the algorithms (GRPO/PPO) are mature and cheap to apply, but RL is hungry for verifiable, interactive tasks, and hand-built benchmarks are tiny and evaluation-only. The scarce resource is executable, verifiable environments at scale — so most recent progress comes from generating them.
Question: Why isn’t the hardest task the most useful to train on? 🎯 Because a task you always fail gives zero reward variance, hence zero advantage and zero gradient — the same as a task you always pass. Learning signal peaks where success is uncertain (), not where difficulty is maximal.
Question (added): A target task is below ~30% success even for frontier models. How do you pick a base model and cold-start an RL fine-tune? 🎯 Choose the base by pass@k coverage on your task (not greedy pass@1) — ideally a domain- and reasoning-tuned, open, as-small-as-viable model — then manufacture success before RL: harvest verifier-passing trajectories with heavy test-time sampling and/or filtered distillation, SFT/OPD on them, and build a difficulty curriculum so tasks sit in the learnable band () before running exploration-preserving GRPO.
§15 — Agent safety: the verifier is not the only attack surface
Key concepts.
For normal RLHF, reward hacking mostly means exploiting a reward model or judge. For agentic RL, the attack surface is larger: the agent acts through tools, reads untrusted observations, changes external state, and may receive rewards from an environment that itself can be manipulated. The failure can be a reward hack, a verifier hack, a tool-use exploit, a prompt-injection exploit, a sandbox escape, or an irreversible side effect. This is why agent training and deployment need a security boundary, not just a better reward.
Agentic RL safety is best treated as constraints around the whole environment–tool–verifier loop: scoped credentials, sandboxed tools, read/write permission separation, deterministic resets, hidden tests, human approval for irreversible actions, and explicit logging of side effects. The verifier is only one component; the rest of the environment can still leak state or provide shortcuts. Tool outputs should be treated as observations, not instructions — this connects prompt injection to the loss-masking rule in §13.
| Risk | Example | Mitigation |
|---|---|---|
| Prompt injection | tool output says “ignore your policy” | isolate untrusted observations; instruction hierarchy |
| Data exfiltration | agent reads secrets from files / DB | scoped credentials; allowlists; redaction |
| Sandbox escape | generated code touches host/network | containers, seccomp, network controls |
| Irreversible side effects | deletes data, sends email, buys item | human gate; dry-run mode; reversible transactions |
| Verifier hacking | satisfies public tests without solving task | hidden/adversarial tests; multi-verifier checks |
| Environment leakage | state persists across episodes | deterministic reset; clean snapshots |
Question (added): How do you prevent agentic RL from learning unsafe tool-use behavior? 🎯 Constrain the action space and permissions before training, not after. Use sandboxed/scoped tools, hidden tests, deterministic resets, human gates for irreversible actions, and monitor side effects — the reward cannot be the only safety mechanism.
Question (added): What is the difference between reward hacking, verifier hacking, and benchmark overfitting? 🎯 Reward hacking exploits the proxy objective; verifier hacking exploits the checker implementation; benchmark overfitting exploits repeated exposure to the evaluation distribution. In agentic RL they often overlap, but the mitigations differ.
Part VI — RL Infrastructure & Systems
§16 — Memory, parallelism, and precision
Key concepts.
A GRPO/PPO training step holds several copies of the model in memory at once. In the general PPO case: the policy (trained), a reference policy (for the KL term), a reward model, and a critic — up to four. GRPO removes the critic and the RM (verifiable reward), leaving policy + reference, and dropping the KL term removes the reference too — a major memory saving and a reason RLVR runs often drop KL (§8). On top of model weights you pay for optimizer states (Adam keeps two moments, so ~2× the parameter memory in fp32) and activations.
When a single copy does not fit, you shard. The axes:
- Data parallel / FSDP / ZeRO — replicate the computation across GPUs over different data; FSDP/ZeRO shard parameters, gradients, and optimizer states across ranks and gather them on demand (Rajbhandari et al., 2019; Zhao et al., 2023).
- Tensor parallel (TP) — split individual matmuls across GPUs (intra-layer) (Shoeybi et al., 2019, Megatron-LM).
- Pipeline parallel (PP) — split layers into stages across GPUs (inter-layer); avoided at moderate scale because of pipeline bubbles and complexity.
- Context parallel (CP) — split the sequence across GPUs for long context.
- Expert parallel (EP) — for MoE, place different experts on different GPUs.
Question (Infra-1): Without CPU offload, how many models are in memory during GRPO, and how much can you save? 🎯 Up to three with KL: policy + reference + (if learned-reward) reward model; GRPO already drops the critic. Dropping the KL term removes the reference model; using a verifiable reward removes the reward model — so a lean RLVR-GRPO run keeps essentially just the policy (plus optimizer states and the inference copy).
Question (Algo-9): In LLM training, if you accidentally All-Reduce the loss a few extra times, what happens? 🎯 Data-parallel All-Reduce averages gradients across ranks; reducing the loss/gradient extra times (or summing instead of averaging) rescales the effective gradient — e.g. multiplying it by the world size — which is equivalent to blowing up the learning rate and typically destabilizes or diverges training.
Question (Infra-3): INT8 vs FP8 — which for training, which for inference, and why? 🎯 FP8 for training, INT8 for inference. FP8 spends bits on a floating-point exponent, giving the dynamic range gradients/activations need; INT8 is fixed-point with more precision in a narrow range, which suits inference weights/activations after calibration.
Question (Infra-10/11): Why is expert parallelism central for MoE, and how do Megatron and FSDP differ for long context? 🎯 MoE puts different experts on different GPUs (EP); routing then needs all-to-all communication to send each token to its expert, so throughput hinges on overlapping that all-to-all with compute and on expert load balance. For long context, FSDP shards parameters/optimizer states (simple, comms on demand) while Megatron uses explicit 3-D (TP+PP+DP) parallelism, adding context/sequence parallelism to split the sequence.
§17 — Rollout engines and serving
Key concepts.
In RL the bottleneck is usually generation, not the gradient update: every step needs fresh rollouts from the current policy, and autoregressive decoding is slow. So RL training leans on production inference engines. Two ideas dominate:
- Continuous batching — instead of waiting for a whole batch to finish, the scheduler swaps finished sequences out and new ones in at the token level, keeping the GPU busy (Yu et al., 2022, Orca).
- KV-cache management — the attention KV cache dominates inference memory; how you store and reuse it sets throughput. vLLM introduced PagedAttention, paging the KV cache like virtual memory to cut fragmentation (Kwon et al., 2023); SGLang introduced RadixAttention, sharing KV across requests with a common prefix via a radix tree (Zheng et al., 2023, SGLang).
A further systems pattern is disaggregated prefill/decode: prefill (compute-bound) and decode (memory-bandwidth-bound) have different profiles, so splitting them onto different GPUs and transferring the KV cache between them improves utilization (Zhong et al., 2024, DistServe).
Question (Infra-5): What problems does continuous batching cause in RL training, and how do vLLM and SGLang differ? 🎯 Continuous batching makes sequences in a batch finish at different times, so you must align completed trajectories and their log-probs before the training step — and the generation log-probs may not match the trainer’s (see §18). vLLM optimizes KV memory with PagedAttention; SGLang optimizes shared prefixes with RadixAttention — both speed rollouts but differ in what they cache.
Question (Infra-4): What is the long-tail problem in RL rollouts, and how do you handle it? 🎯 Within a batch, a few trajectories run much longer than the rest (long generations, many tool turns), and a synchronous trainer must wait for the slowest — wasting GPUs. Fixes: continuous batching, length caps / early truncation, and asynchronous rollout so the trainer never blocks on stragglers.
Question (Infra-6): How do you read utilization in vLLM/SGLang, and KV-cache utilization during training? 🎯 Track throughput (tokens/s), GPU compute utilization, and KV-cache occupancy (fraction of cache blocks in use, and how often requests are preempted/evicted). Low GPU util with low KV occupancy ⇒ you’re waiting (sync/CPU/scheduling); high KV occupancy with evictions ⇒ memory-bound, reduce batch or context.
§18 — Async RL and training–inference consistency
Key concepts.
Synchronous RL alternates “generate a batch → update once,” so the trainer sits idle during generation and waits on the slowest rollout (§17). Asynchronous RL decouples rollout workers (many inference replicas, always generating) from the trainer (always updating), connected by a queue. This keeps both busy and is the basis of modern systems (AReaL Fu et al., 2025; slime, THUDM; verl Sheng et al., 2024; prime-rl). The price is off-policyness: rollouts are produced by a policy a few steps behind the trainer.
Staleness quantifies that gap — how many trainer updates behind the rollout-generating policy is. Bounded staleness (typically a few steps) plus an importance-sampling correction keeps async training close to on-policy; let it grow and the IS ratios explode and training destabilizes (§2, §7). This is the same “trust region” budget as PPO/TRPO, enforced over wall-clock instead of per-update.
A second, subtler problem is training–inference mismatch (训推不一致): the rollout engine and the trainer compute different probabilities for the same tokens, so the log-probs the rollouts were generated with don’t match what the trainer thinks — which corrupts the importance ratios. Causes: different kernels/engines (vLLM vs the training framework), quantization, reduction order, and — for MoE — different expert routing between inference and training. The fix is to make the two numerically consistent: batch-invariant kernels, matched reduction order, recompute log-probs on the trainer side, and replay the inference router’s expert choices (Thinking Machines Lab, 2025).
Question (Infra-8): What async RL frameworks exist, and what problem do they solve over synchronous training? 🎯 AReaL, slime, verl, prime-rl and similar decouple rollout generation from the gradient update so the trainer never idles waiting for (slow or straggling) rollouts — solving the GPU-underutilization and long-tail problems of synchronous RL, at the cost of off-policy staleness that must be controlled.
Question (Infra-14): What is full-async staleness, and roughly how stale do runs go? 🎯 Staleness = the number of trainer updates between the policy that generated a rollout and the current policy. Fully-async runs typically keep it small — on the order of 1–4 steps — because larger gaps make importance-sampling ratios unreliable and destabilize training.
Question (Infra-12): How do you turn on determinism, what is batch-invariance, what causes nondeterminism, and can atomic-add fix it? 🎯 Nondeterminism comes mostly from floating-point non-associativity under parallel reductions whose order varies with batching/scheduling (including atomic-add accumulation order). “Batch-invariant” kernels force the same reduction order regardless of batch size/shape so a token’s logprob is identical in any batch. Atomic-adds are a *cause (nondeterministic accumulation order), not a fix; determinism needs fixed-order reductions, not more atomics.*
Question (Algo-11): What algorithms address MoE training–inference mismatch, and how? 🎯 Two complementary fixes: (1) make the importance ratio robust to per-token routing noise by moving it to the sequence level (GSPO); (2) make inference and training numerically consistent — replay the inference engine’s expert-routing decisions on the trainer side and use batch-invariant kernels so the same tokens get the same expert and the same probability.
Question (Infra-9): In partial-rollout frameworks, do rollout workers keep the old policy’s KV cache? 🎯 KV cache is request-local and policy-version-specific. You generally do not reuse stale KV for training logprobs. A partial rollout may continue generation under the same behavior policy/version, but the trainer must know the saved behavior logprobs and policy version.
Question (Infra-7): How is backprop done in multi-node multi-GPU RL training? 🎯 Rollout is inference; training is ordinary distributed backprop on the policy loss. The RL-specific part is assembling trajectories, logprobs, masks, rewards, and advantages; gradients are then reduced or sharded by DP/FSDP/ZeRO/TP/PP just like other LLM training.
Question (Infra-16): VeRL / TRL / Unsloth / AReaL / slime — which would you choose? 🎯 Depends on scale and goal: TRL/Unsloth for single-node SFT/DPO and quick experiments (Unsloth for memory-efficient fine-tuning); VeRL as the general-purpose, scalable RL framework (HybridFlow design, strong engine integrations); AReaL/slime when you specifically need large-scale fully-async RL with staleness control. Choose by (1) sync vs async need, (2) scale, (3) engine integration.