Paper summary · Sept 2026
Distillation Scaling Laws
https://arxiv.org/pdf/2502.08606
Ankifying
- Our results show that distillation can not produce lower model cross-entropies than supervised learning when both learning processes are given enough data or compute. However, distillation is more efficient than supervised learning if both of the following are true: 1. The total compute or tokens used for the student is not larger than student size-dependent threshold given by our scaling law A teacher already exists, or the teacher to be trained has uses beyond a single distillation
- Canonical Chincilla optimal scaling laws rules of thumb
- Power law vs broken power law funcitonal forms and their intuition
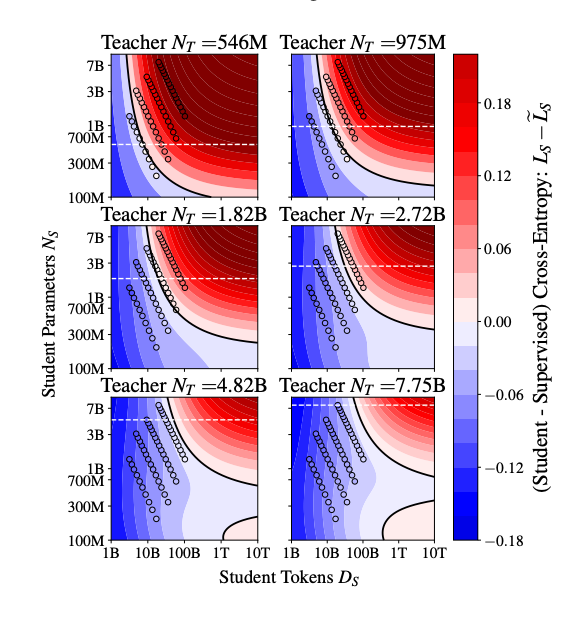
- For a fixed data budget, as the student size increases, teacher cross-entropy should be decreased as a power law
- Supervised learning always outperforms distillation given enough student compute or tokens.
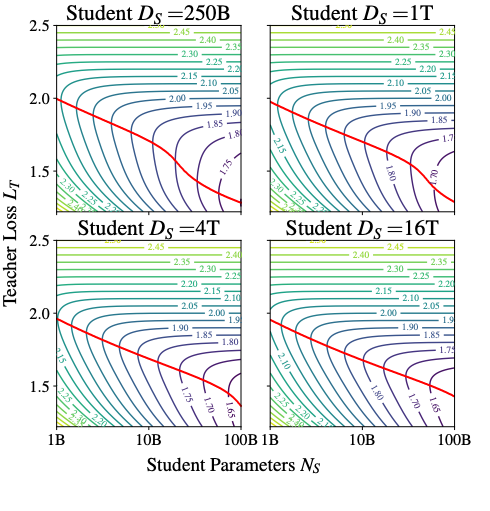
- For a fixed data budget, as the student size increases, teacher cross-entropy should be decreased as a power law
- Types of tests one runs for scaling laws, what is held in placed and what varies