Paper summary · Oct 2026
Improving Data Efficiency for LLM Reinforcement Fine-tuning through Difficulty-targeted Online Data Selection and Rollout Replay
- Authors: Yifan Sun, Jingyan Shen, Yibin Wang and Huan Zhang
- Link/DOI: chrome-extension://afikdfhpphmiponfgggpopedhllgaeni/viewer.html?file=https://arxiv.org/pdf/2506.05316
- Date Read: 2026-10-19
- Tags:
TL;DR
1. Problem Statement
- The most effective approach for fine tuning LLMs is currently through RL. However, RL is extremely resource-intensive and existing work has largely overlooked the data inefficiency of it. In this paper, the authors introduce two techniques to improve the data efficiency of LLM RL fine tuning:
- Difficulty targeted online data selection - through adaptive difficulty they prioritize questions that are more likely to yield informative learning signals.
- Rollout Replay
2. Methodology / Architecture
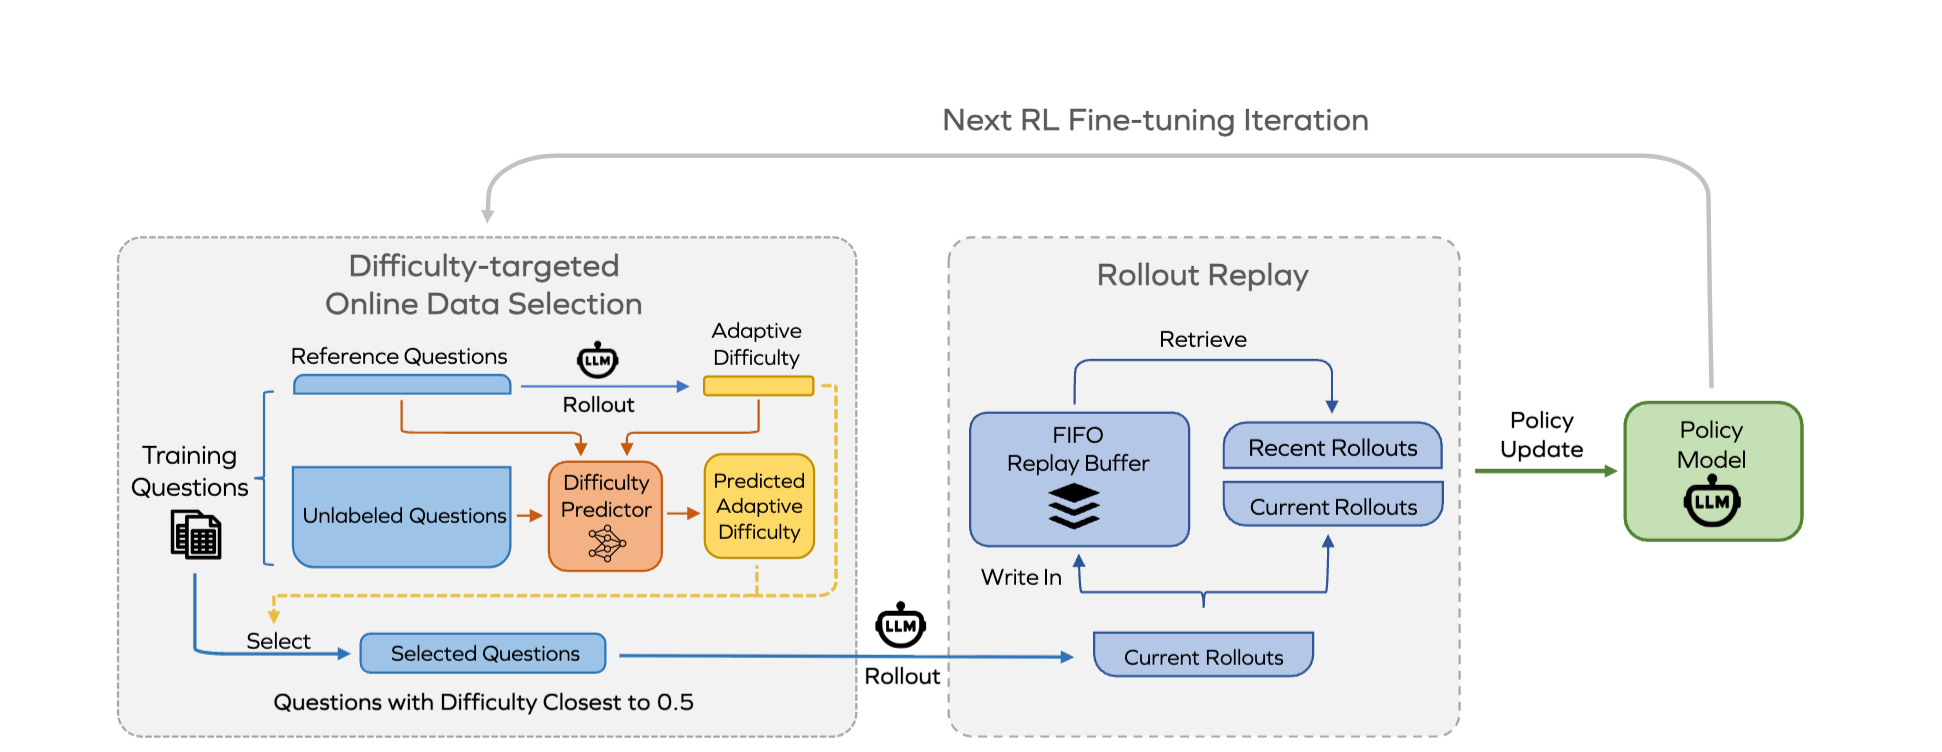
- Difficulty Targeted Online Data Selection (DOTS) - Samples with 0.5 success probability are maximally informative. The authors try to select these for efficient training. TO that end, they execute multiple rollouts for a small reference set and compute groung truth adaptive difficulty for these. Then, the difficulty of the rest of the training set is estimated by comparing them to the reference set
- The authors explicitly call out the importance of this approach being online, the non-stationarity is crucial given the evolving state of the model.
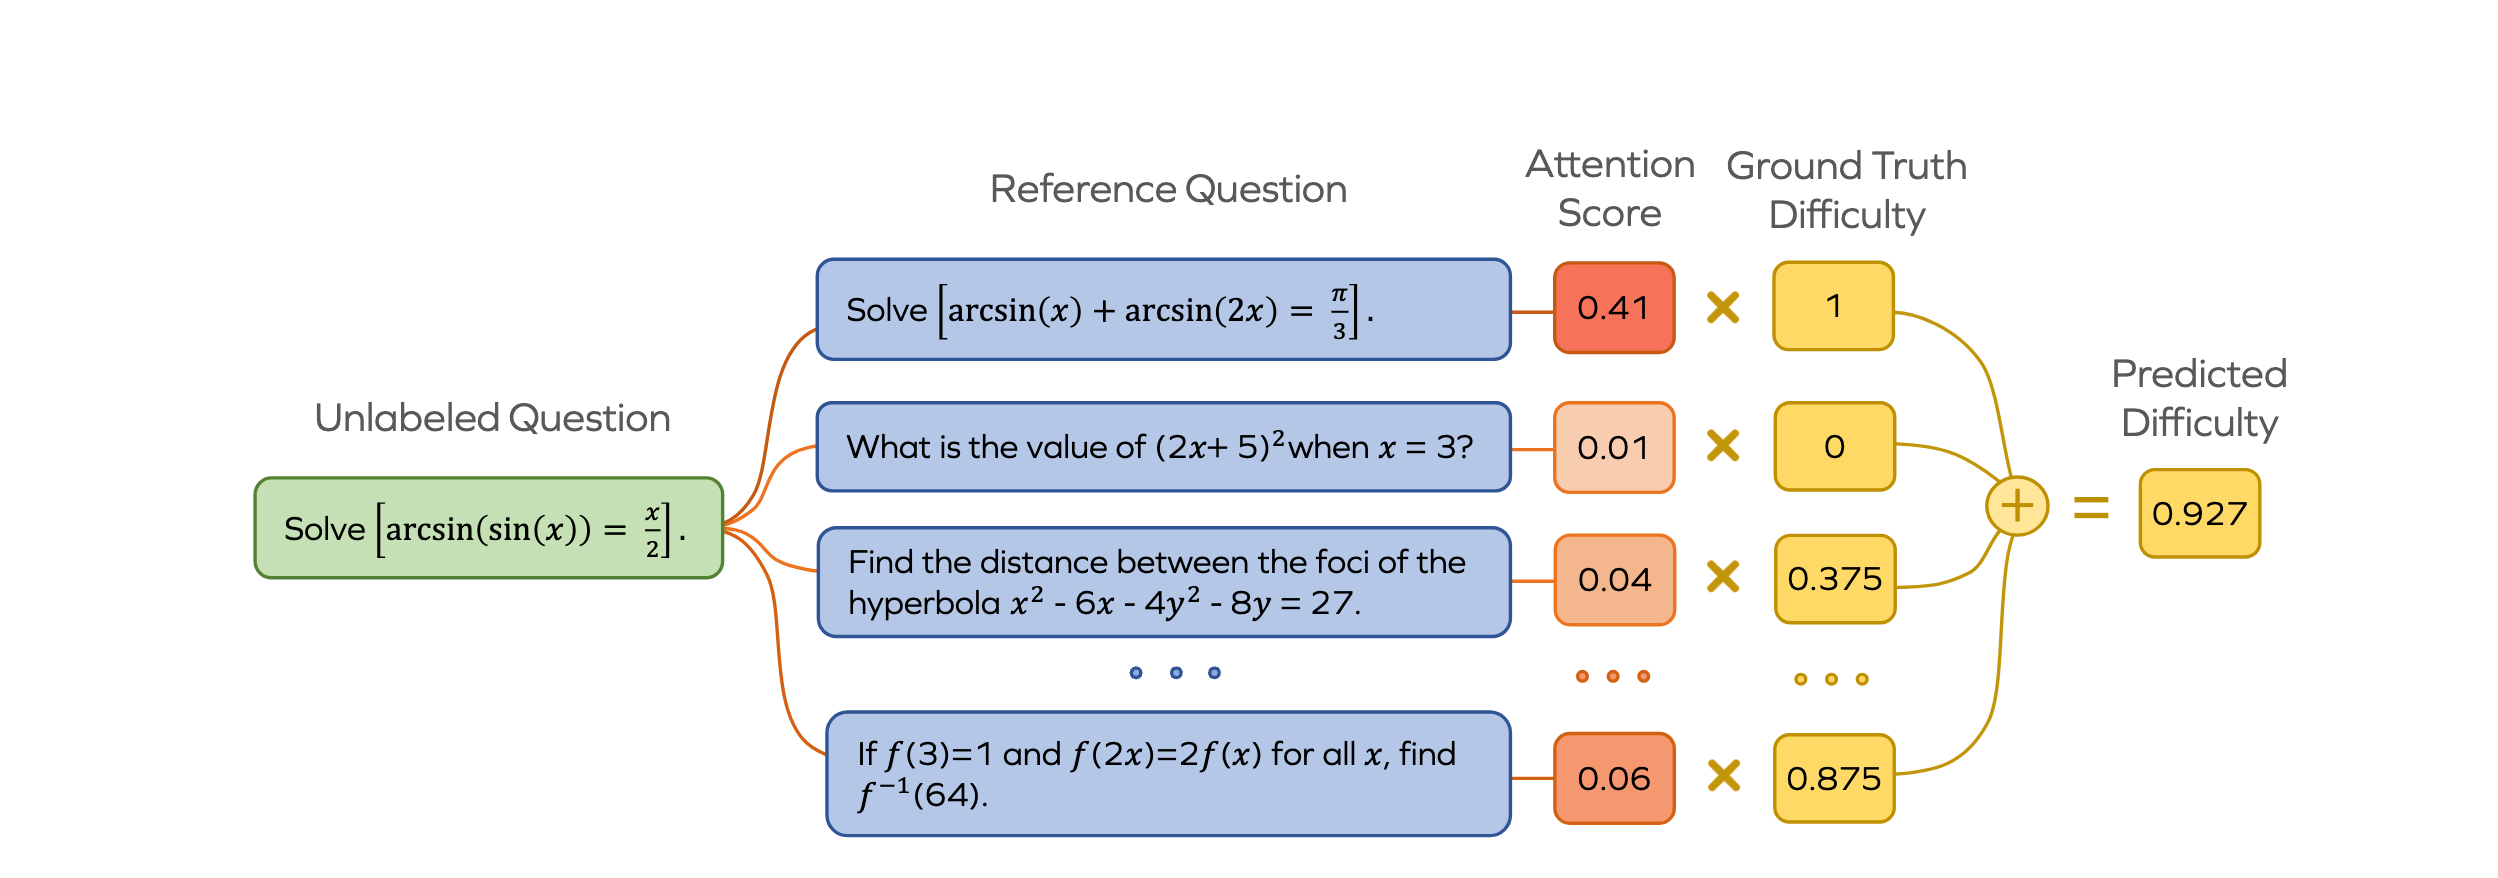 Claude - Here please fill in the details of the adaptive scaling, how the diffficulty is calculated for the subset, then how these are used through embedding to give predicted for the rest of the samples + calibration. Be concise, the equations are nearly sufficient.
- The authors explicitly call out the importance of this approach being online, the non-stationarity is crucial given the evolving state of the model.
- Rollout Replay (RR) - at each training step they generate rollouts and reuse past rollouts from recent steps. They use a bounded FIFO buffer. Naively reusing past rollouts introduces bias into the policy gradient estimation, they therefore provide a modified GRPO loss which uses importance sampling wrt the original policy under which the rollouts where originally created
The full algorithm:
Algorithm 1 GRPO with DOTS and RR
Require: Initial policy model , reward model , training dataset , target difficulty , batch size , total steps , reference set size , sampling temperature , adaptive difficulty prediction framework DiffPred (§4.1), fresh rollout fraction , buffer capacity
1Initialize replay buffer2Set3for step do- // Adaptive difficulty prediction
4Sample reference set uniformly at random, where5for each do6Generate outputs7Compute rewards for and difficulty score
8end for9Predict adaptive difficulty for all10Sample rollout batch of size from according to:11for each do12Generate outputs13Compute rewards for and group average reward14Obtain advantages and policy probabilities for
15end for- // Rollout Replay and update
16Sample samples from buffer to complete batch if17Update policy using modified GRPO objective on batch- // Store informative rollouts in buffer
18Add to for19Remove the oldest samples from until20Set
21end for
3. Results & Performance
- 23-62% reduction in fine-tuning time while maintaining the same ultimate level of performance
- They show that the pearson correlation between predicted and actual adaptive difficulty sits above 0.7 for all samples, which is great!
- 25% more “effective questions” than baseline (effective = strictly within 0 and 1 success. No zero gradient samples)
4. Limitations
- Only tested on small models with non-agentic tasks. Experience replay with associated environments is harder
- How is the replay buffer different from “repeating epochs”?
- If it’s not, can we somehow leverage lessons from this to “batch buidling” in Pre-training where we aim to ahve a representative mixture of samples in each training step, to reduce catastrophic forgetting.
5. Personal Takeaways / Action Items
- DOTS accelerates convergence while RR reduces per-step cost, both of these are effective ways of improving RL efficiency
- DOTS outperforms external difficulty labels (i.e AI as a judge, methods without access to ground truth/internal representations)